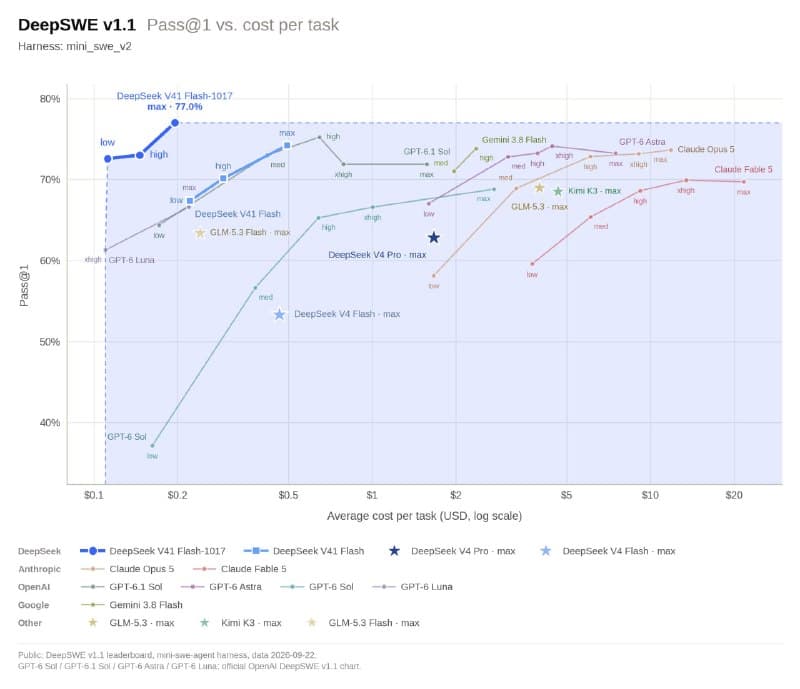
For some time now, if you want to use the API of Zhipu, China’s largest AI company and the maker of the GLM series, without a hitch, you have to log in at 10 a.m. Even after raising prices by 83%, supply still cannot keep up. Chinese developers joke that it is “harder to get than Moutai.”
The landscape was the exact opposite a year ago. ByteDance’s Doubao cost less than 0.01 won to process a paragraph of text, and Alibaba was giving away hundreds of thousands of won worth of usage for free. DeepSeek was an icon of the “open source” philosophy of making its technology available for anyone to use. The mood that dominated China’s AI industry then could be summed up in two words: “the righteousness of openness.”

In just one year, everything flipped. Alibaba’s latest model, Qwen 3.6 Plus, became closed and available only through its own products, while Zhipu’s GLM5.1 is proving the power of closed models by leading the Chinese market. MiniMax 2.7 carries the name “open source,” but using it for business requires separate permission. It follows the same formula as Red Hat, which became a multibillion-dollar company by layering paid enterprise services on top of Linux, a free operating system. The pattern is clear. The highest-performing models are closed, while only smaller models are released under limited conditions.
If you read this shift only through the lens of the US-China technology Cold War, you miss the point. The Cold War is merely the catalyst. At its core, this is a declaration that AI models have finally become products that make real money. And three forces are driving it forward: cost, distillation, and geopolitics.
The first pressure is cost. The amount of text AI processes worldwide each day exploded from roughly 1.2 trillion words in early 2024 to 1,400 trillion words in March 2026, an increase of more than 1,000 times. At this scale, offering it for free is not charity. It is suicide.
There is a story in the investment world that “AI services are moving toward a structure where adding one more user costs almost nothing.” Reality is the exact opposite. Small AI models now run on smartphones. But the AI services drawing attention these days—the so-called “agentic AI” that thinks through multiple steps on its own, calls external tools, and combines that with real-time search—still consume the computing power of dozens or even hundreds of large servers. The real source of the explosion is not small AI running on smartphones, but large AI running complex reasoning on cloud servers. In 2024, the bottleneck was GPUs, the chips dedicated to AI computation. Now the bottleneck has moved up to the service layer on top of those chips.
In the early days of the internet, people said, “Information wants to be free.” News was free, and people said blogs would replace the press. As newsrooms disappeared one by one, the survivors put up paid subscription walls. The New York Times, The Economist, The Washington Post. Once it was proven that good content could make money, “free” came to an end. What is happening with AI open source today is following exactly the same path. “The righteousness of openness” was a luxury from the time when models did not yet make money. The moment demand overwhelms supply, the justification for openness evaporates.
The second pressure, distillation, is a training method that collects large quantities of answers from a large AI model and feeds them to a smaller model. It is like tasting a master chef’s dish and recreating the recipe. In February this year, Anthropic named DeepSeek, Moonshot, and MiniMax in an official report and called the use of 24,000 fake accounts to send 16 million questions an “industrial-scale distillation attack.” In early April, OpenAI, Anthropic, and Google activated an information-sharing system on Chinese companies’ distillation through the FMF (Frontier Model Forum), which they created together. On the surface, this is about protecting intellectual property.
Elon Musk hit the nail on the head. “What kind of spectacle is it for Anthropic to be outraged that China took what Anthropic took from human programmers?” The fact that US AI companies trained their models on GitHub code, Stack Overflow answers, and writing produced by hundreds of millions of people is itself distillation in the broad sense. China distilling those models again is copying a copy, and no one has the standing to claim the moral high ground.
The third pressure is geopolitics. The essence of the FMF is the formation of an international cartel that decides who can use this technology and who cannot. The moral argument over distillation is secondary. The core issue is the framework of those rules, which is highly likely to be institutionalized between 2026 and 2027.
As the three pressures work together, the global AI ecosystem will settle into a dual structure: “lock the highest-performing models behind paid APIs and release only smaller models under limited conditions.” Just as AWS, Azure, and GCP divided the cloud market among themselves, the AI services market could also settle into an oligopoly dominated by a small number of large players.
But history has repeatedly shown that closure is not the end. When Oracle neglected the MySQL database it acquired, an alternative called MariaDB grew. When Redis changed its terms of use, a copy called Valkey emerged. Meta is moving in the opposite direction, continuing to release its AI model Llama for free and undercutting the paid premiums of its competitors. The moment the number-one companies close their doors, the number-two and number-three companies will go all in on releasing their models for free, even more aggressively.
DeepSeek, the main culprit behind the distillation attacks, may actually be advantaged in this environment. Even if it began by copying, it accumulated the ability to train AI in the process. Distillation is not simple copying. In the process of reconstructing and optimizing the answers of a large model, a company internalizes pipelines for refining data, know-how for designing the order of training, and systems for evaluating performance. It is the process by which a cook who once copied recipes becomes a chef with a taste of their own. What is more, models that have already been released cannot be taken back. DeepSeek V3, Qwen 3.5, and Google’s Gemma 4, released under a permissive license, have been copied across hundreds of thousands of servers. Closing the door is effective only for future models.
The impact of this structure on each region is clear. In Korea, the most dangerous position belongs to startups that took public models from Qwen or DeepSeek and built their own services on top of them. The moment updates to the original model stop, time turns against them. Competitors switch to the latest models, while services dependent on the original get trapped on an outdated version.
There are two ways to survive. One is to build a defensive wall of proprietary data and create an independent service in a specific domain. The other is to control the “multi-model brokerage” infrastructure that chooses between US and Chinese models depending on the situation—in other words, the traffic-control role of finding the optimal route among multiple AI models. As the technological divide between the US and China deepens, the value of this intermediary connecting the two sides will actually rise.
The situation in Southeast Asia is even more dramatic. Startups in Indonesia and Vietnam have already built services on top of small Chinese AI models, and Southeast Asia as a whole is highly likely to be incorporated into China’s AI sphere of influence. The geopolitics of technology creates spheres of influence in ways that differ from physical borders.
The structure will become clear: both the US and China close their highest-performing models, while ecosystems of large and small satellites split off around them. The battlefield will shift away from the completed AI model itself and toward control of the data used for training and the training process.
Let’s imagine. In 2028, a company releases an AI that delivers overwhelming performance in reading medical images. A competitor tries to reproduce it but runs into a wall. The model’s blueprint is in a paper, and there is enough computing power, but they do not have millions of diagnostic records from specialists or the know-how to train the model on them. It is like having the blueprint for a semiconductor but being unable to produce a chip without the key manufacturing equipment. It will be a world where not just the AI model itself, but the entire training process, is secret.
Models are copied, and algorithms spread through papers. But in a world where even the raw material—data—is locked away, the more closed models become, the more open the competition becomes around the infrastructure that actually runs AI. No matter how good a model you have, it ultimately has to run on someone’s servers. The next ruler of the game will not be the side that owns the best model, but the side with the route that can move any model at the lowest cost and highest speed.
This route is the intermediary infrastructure that finds the optimal path among multiple models, the traffic-control layer. Beneath the war over the raw materials of data and training, who is quietly laying the pipes?